
Table of Contents
ChronoLLM says pre-training of its 16-billion-parameter mixture-of-experts model is nearly complete, with early results putting it ahead of AQR's point-in-time language model. Built on Bittensor by Subnet 38, ChronoLLM-16B is intended for researchers who need AI to analyze historical information without knowing what happened afterward.
The team says the upcoming model scores 12.5% higher than AQR's PIT-4B on the Open LLM benchmark, with a 22% advantage at the 2013 training cutoff. Those comparisons are ChronoLLM's own reported results. It also says the 16B model is eight times larger than its predecessor and scores 22% higher.
Point-in-time models address lookahead bias: the risk that later information contaminates a historical test. A conventional model analyzing an old company report may already know the company's subsequent performance. Restricting training data to a historical cutoff gives researchers a way to evaluate signals using information available at that time.
ChronoLLM says its early model vintages outperform every point-in-time model in its comparison at each cutoff through 2020. Its chart plots Open LLM Leaderboard v1 mean scores by training-data cutoff, placing ChronoLLM-16B above AQR PIT-4B and the earlier ChronoLLM 2B model.
The larger model also expands how much text researchers can process at once. ChronoLLM reports a 16,000-token context window, compared with 2,000 tokens for AQR's model, and says that is enough to handle a full earnings call in one pass.
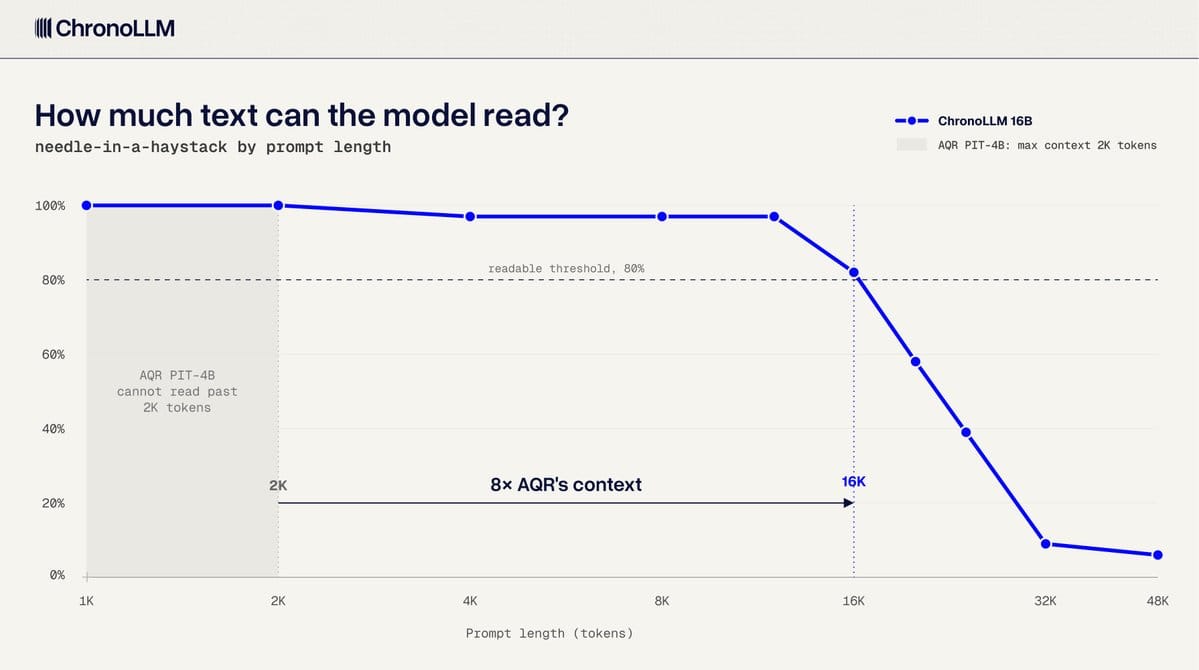
The accompanying needle-in-a-haystack test measures whether the model can retrieve information embedded in a longer prompt. The chart shows retrieval near 100% through roughly 12,000 tokens and just above its marked 80% threshold at 16,000 tokens, before falling sharply at longer inputs.
The development follows ChronoLLM's September product launch. Operated by Crunch, ChronoLLM offers historical vintages going back to 1999, using a rolling 20-year training window and walk-forward training. Its product includes post-cutoff leak probes so researchers can test a model's time boundary, along with self-hosting for teams that need to keep financial data and strategies on their own infrastructure.