
Table of Contents
Chutes has added DeepSeek V4.1 Flash to its inference platform, giving developers a lower-cost option alongside DeepSeek V4 Pro for running AI agents. The Bittensor Subnet 64 platform recommends using Flash for routine calls and Pro for harder tasks, with both accessible through the same API key and endpoint.
Flash costs $0.30 per million input tokens and $1.20 per million output tokens, compared with V4 Pro's $0.85 and $2.65. That makes Flash roughly 65% cheaper for input and 55% cheaper for output at Chutes' listed rates. Cached input costs $0.03 per million tokens.
Developers can search through the Chutes model listing. It uses the OpenAI-compatible API base URL.
Both models have a 1 million-token context window. Flash's backbone has 552 billion parameters, with 8 billion active while processing input and 16 billion during output generation, versus Pro's 1.6 trillion parameters and 49 billion active. Activating only part of a model for each token reduces the computation needed compared with using all its parameters at once.
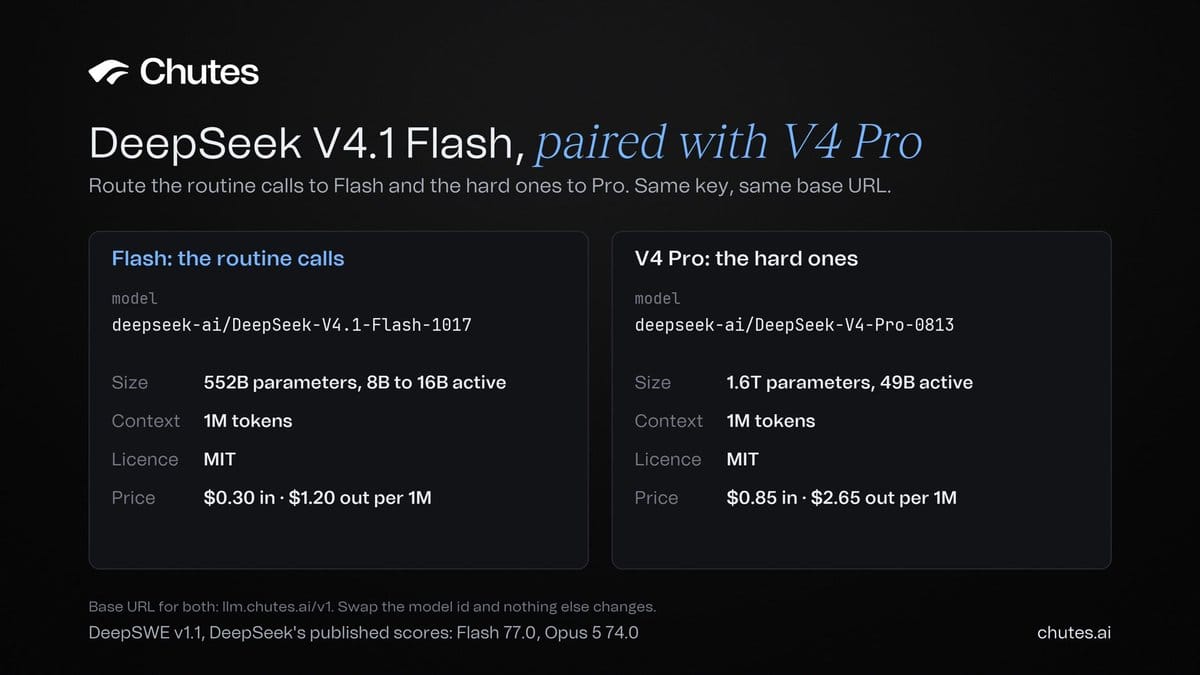
The listing is the 1017 update to DeepSeek's V4.1-Flash family, whose architecture allocates different amounts of computation to reading context and generating responses. The model's weights are available under the MIT license.
In DeepSeek's published evaluations, the 1017 model scores 77.0 on DeepSWE v1.1, compared with Opus 5's 74.0, and leads the listed models on Agents' Last Exam with 35.4. It scores 42.3 on Terminal-Bench 4.0, behind Opus 5's 51.8. DeepSeek used Mini-SWE-V2 for the software-engineering test and Claude Code for the terminal evaluation.
Chutes recommends retaining Pro for the longest terminal sessions while directing everyday agent calls to Flash. The addition follows its rollout of Qwen3.8 Max and DeepSeek V4.1 Pro as the platform ended subscription renewals and moved those new models to pay-as-you-go access.


