Table of Contents
Figure has introduced Helix 2.5, a new version of its onboard humanoid AI system, after testing the model across 30 rented Bay Area homes that were not included in its training or adaptation data.
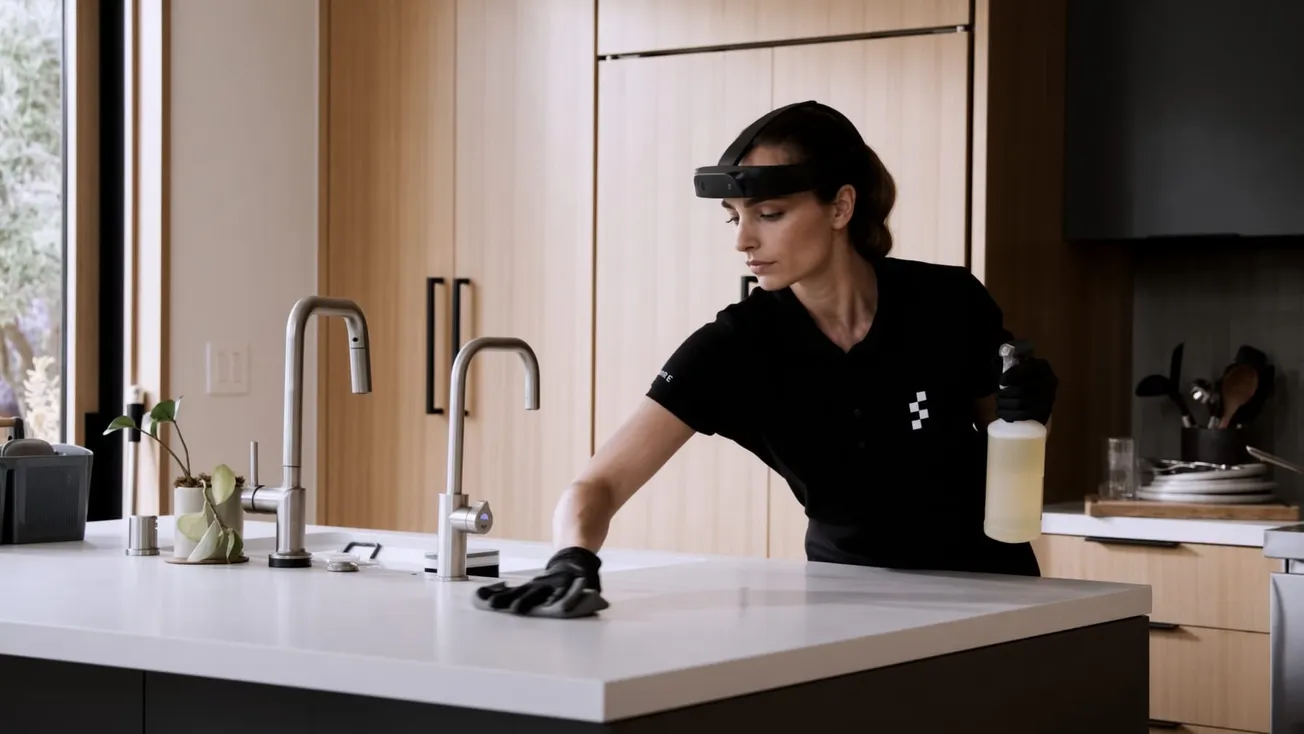
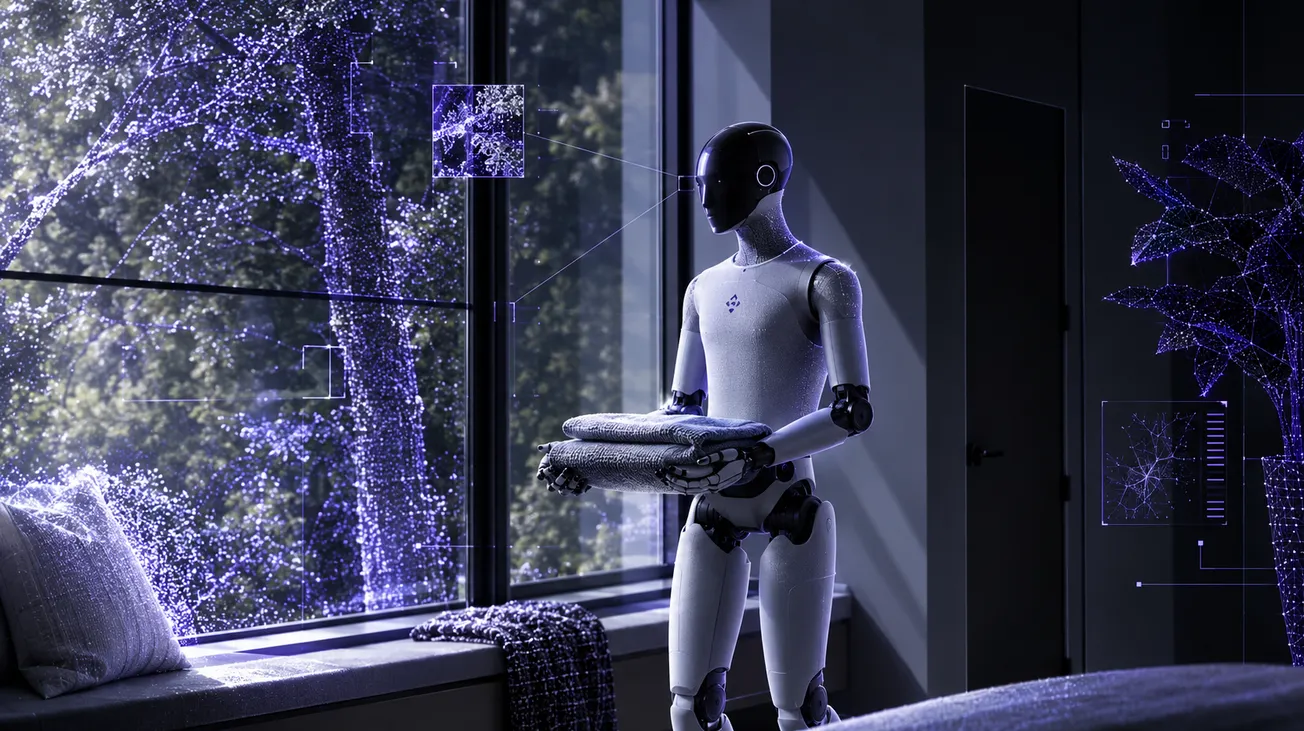
The trial tested whether a humanoid can enter an unfamiliar home and perform useful work without a new data collection round in that environment. In Figure's evaluation, one fixed Helix 2.5 checkpoint attempted three household tasks across the 30 homes: tidying scattered toys into a basket, folding towels and placing them in a basket, and making a bed by positioning pillows and smoothing the comforter.
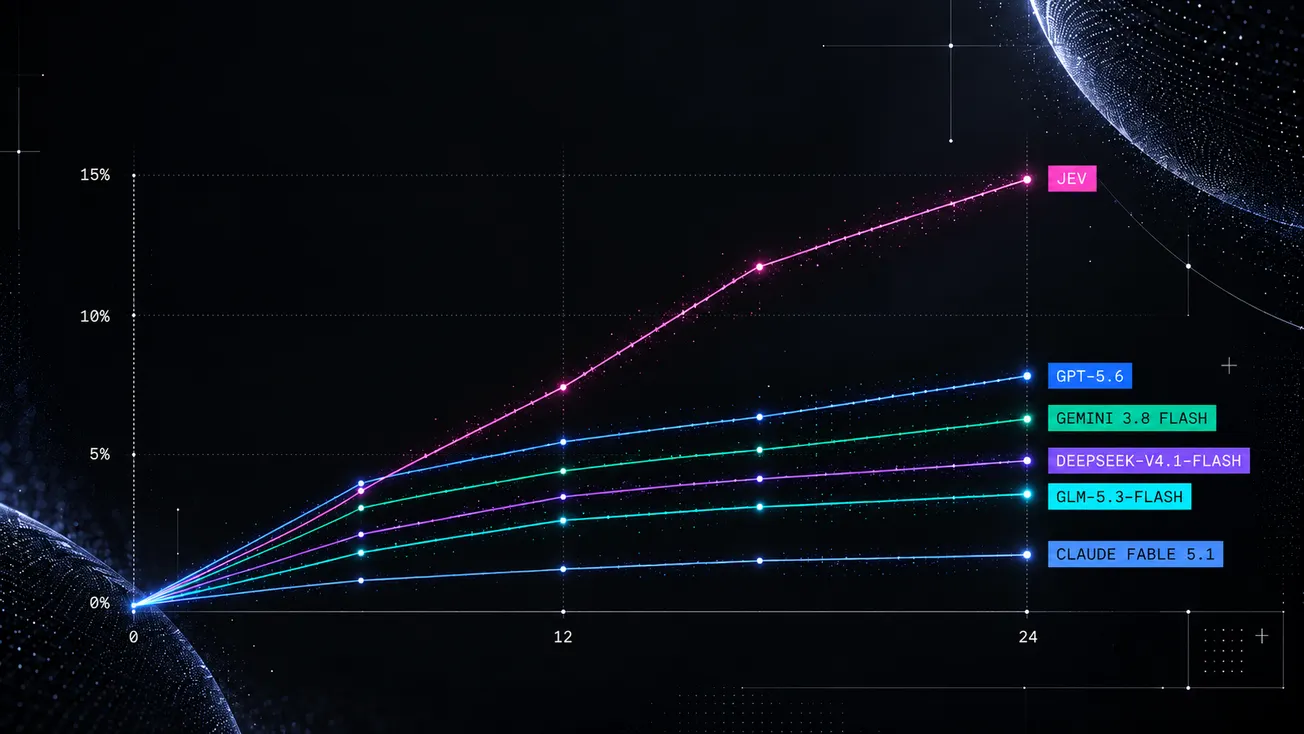
The result was a 56% zero-shot success rate for the Index-pretrained version of Helix 2.5, compared with 9% for a model trained from scratch on the same task-specific data. Figure framed the gap as evidence that pretraining on broad human behavior, rather than collecting more teleoperation data in every new environment, is doing much of the transfer work.
"The holy grail for robotics is being able to generalize: doing work in unseen places," Figure founder Brett Adcock wrote.
Here's 4 hours of our robot doing zero-shot work in 30 rental homes pic.twitter.com/N10vHdGuq4
— Figure (@Figure_robot) September 17, 2026
Figure Tests Household Generalization Beyond the Lab
Helix is Figure's vision-language-action stack for controlling its humanoid robots. The original Helix model, introduced in February 2025, focused on upper-body control and object manipulation. Helix 02, released in January 2026, extended the system to full-body loco-manipulation, allowing the robot to coordinate walking, balance, perception, and manipulation as one continuous behavior.
Helix 2.5 builds on that line of work with a clearer focus on transfer. Instead of demonstrating a behavior in one trained kitchen, warehouse, or lab setup, Figure attempted to show that the same learned behavior can carry into homes the robot has not seen before.
Household robotics is less controlled than most public humanoid demos. Furniture layouts vary, objects appear in unpredictable places, beds and couches have different dimensions, and the robot has to reposition its entire body to see, reach, lift, fold, and recover from errors. A humanoid must coordinate perception, locomotion, stance, balance, and manipulation in an unfamiliar space, not just recognize an object or move a hand.
No data was collected in any of the 30 evaluation homes before the evaluation. The objects used in the trial were also held out from the task-specification data, with Figure saying an AI model and human review were used to verify that the toys, towels, and bedding did not appear in the adaptation set.
What Helix 2.5 Had to Complete
Figure's test used strict success criteria - no partial credit here!
For the living room task, the robot had to pick up all 13 to 15 toys scattered in the scene and place them in a basket. For the towel task, it had to fold all towels and place them in a basket, with folds graded by corner alignment. For bed making, it had to place both pillows near the top of the bed and pull the comforter smooth, including both comforter corners.
Each task used the same checkpoint across all homes. No weights were adapted to the evaluation homes or objects, and no evaluation rollout data was used for checkpoint selection.
That is the basis for the company's "zero-shot" claim. Zero-shot refers to the 30 evaluation homes and manipulated objects. Helix 2.5 was still fine-tuned on the three task behaviors elsewhere before being deployed into the rented homes. Figure is only claiming that three trained household behaviors were transferred to unseen home environments without additional local training, not that it has a general household robot able to perform arbitrary chores on command.
A 56% success rate is not a consumer product. Nearly half of the trials still failed, and the task set was narrow: toys, towels, and beds. The evaluation also came from Figure itself, not an independent benchmark.
Still, the trial is a more useful signal than a single polished demo because it tests the same model across many physical spaces. Most humanoid videos still happen in familiar environments where the robot, the objects, and the layout are already part of the development loop. Figure is trying to show that its models can leave that loop.
Index Pretraining Is the Core Claim
The center of the Helix 2.5 announcement is Figure's Index dataset, a global data program built around recorded human behavior.
 Tristan Hillerich
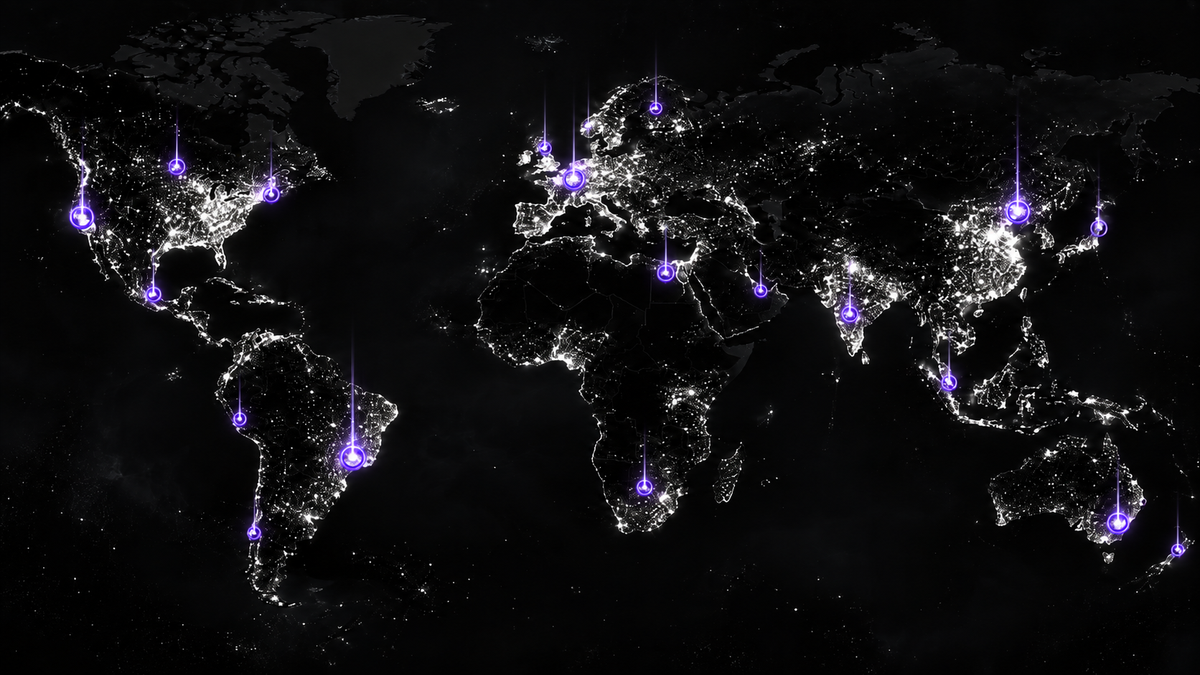
Index is now generating roughly 35 minutes of new human experience per second, giving the company a large source of video data for training humanoid models before the robot encounters a specific deployment environment.
Figure tested the value of that pretraining by comparing two policies trained on identical task-specification data. One began from random weights. The other began from the Index-pretrained Helix 2.5 model where architecture, optimization, hyperparameters, downstream data, and evaluation were held fixed.
The pretrained model succeeded on 56% of zero-shot trials. The scratch-trained model succeeded on 9%.
Helix 2.5 also matched a representative Helix 02 task success rate while using about half as much task-specific data, and did so across 30 unseen homes rather than the environment where the older policy had been trained. Figure described this as behavior specification becoming "2x cheaper" while its scope expanded "30x."
The implication is that more of the useful behavior is being learned during broad pretraining, while smaller amounts of robot-specific or task-specific data are used to shape that general capability into a particular behavior.
Figure also reported what it described as a human-to-humanoid transfer scaling law. Figure trained four models on nested subsets of Index spanning an 8x increase in pretraining data, then measured downstream robot-action prediction after fine-tuning. Figure said loss improved smoothly enough that smaller runs could forecast the largest run's test loss to four decimal places before training.
That does not prove the robot can perform any home task, but it does support Figure's broader argument. If human-behavior data scales predictably, larger Index datasets and more compute could make downstream robot learning more efficient.
What the Demo Shows, and Where It Falls Short
The Helix 2.5 demo is an argument about robotics scaling. Beyond folding towels or making a bed, Figure is trying to prove that humanoid behavior can be learned from large-scale human experience and transferred into new physical settings, instead of rebuilding one house, one workstation, or one task at a time.
A humanoid that works only in a staged environment is useful for demonstrations, but expensive to scale. A humanoid that can enter unfamiliar spaces and use prior knowledge to recover from small differences in layout, lighting, object placement, and surfaces would be far more practical.
Figure's reported self-correction examples point in that direction. Helix 2.5 can step back, change stance, move around a bed, and continue after imperfect manipulation attempts. Long-horizon household tasks often fail because small errors accumulate. A robot that can recover from some of those errors is more valuable than one that only succeeds when every grasp and step goes exactly as planned.
But the limitations are just as important as the progress. The homes were all rented in the Bay Area, which raises fair questions about how much variation the trial captured. The tasks were selected and trained in advance. Figure also graded its own evaluations.
The 56% figure should therefore be read as an early generalization result, not evidence that household humanoids are ready for broad use.
Figure is nevertheless pairing that work with an aggressive scaling plan. It has committed $3.5 billion of compute to training Helix, while Index continues to add human behavior data at high volume. If the Helix 2.5 results hold up across more tasks, more geographies, and independent testing, the announcement will be remembered less for the three chores themselves and more for the evidence that pretraining can reduce how much environment-specific teaching humanoids need.
For now, Helix 2.5 gives Figure a stronger generalization story than a single in-lab video. It shows a robot model transferring three whole-body behaviors into 30 unseen homes, while also making clear how much work remains before a humanoid can be trusted to handle open-ended household work on its own.