Table of Contents
SpaceXAI has introduced Grok 4.7, a frontier model focused on coding, knowledge work, and longer-running agentic tasks.
SpaceXAI said Grok 4.7 is its most capable model for software engineering and professional workflows, with stronger self-checking, better long-context management, and a new safeguard stack. It is available today in Cursor, Grok Build, the Grok API, third-party coding harnesses, model routers, and cloud platforms.
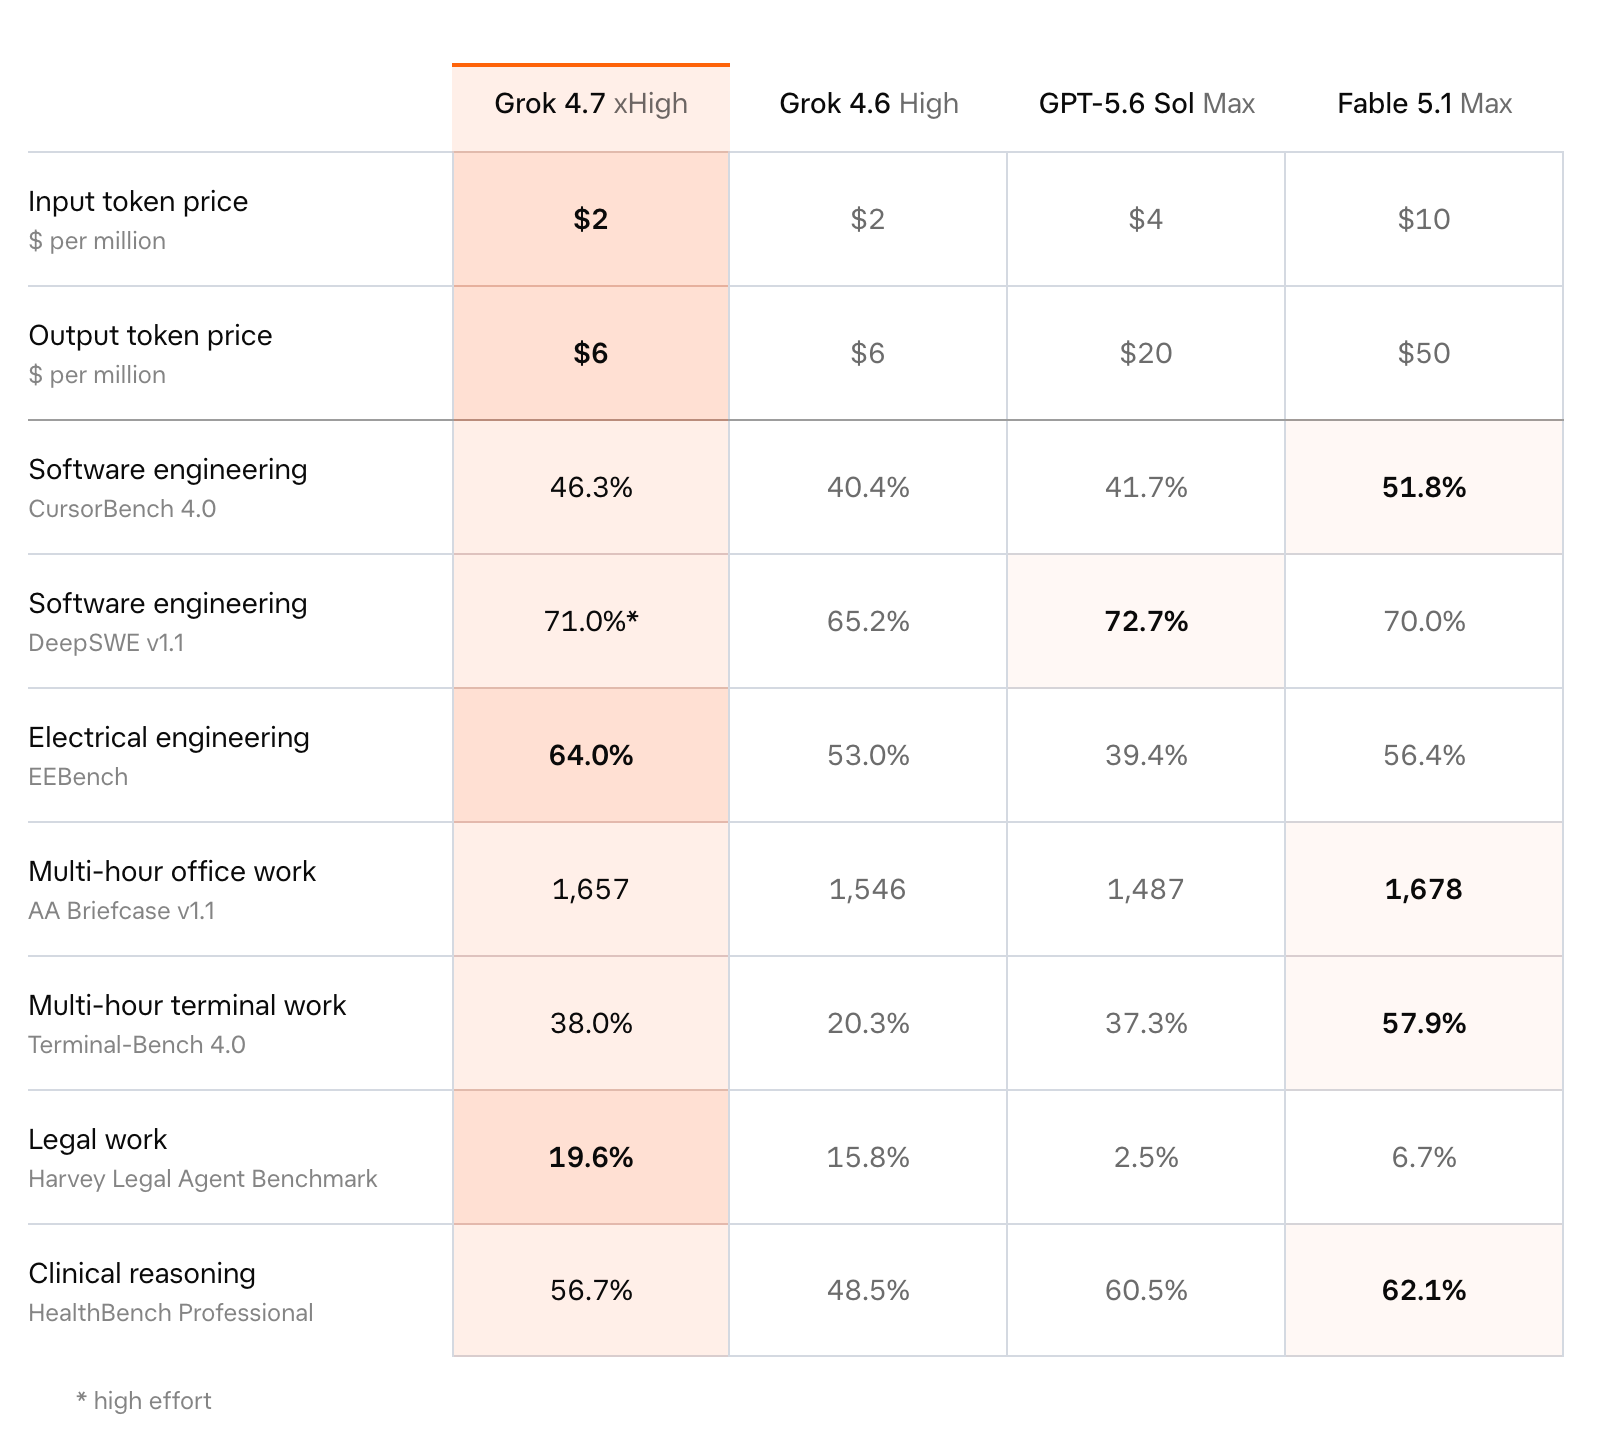
Grok 4.7 is a direct upgrade over Grok 4.6, running at the same base price and speed as Grok 4.6, and starting at $2 per million input tokens and $6 per million output tokens. A faster variant doubles the output speed at twice the price.
Grok 4.7 runs on a larger base model than Grok 4.6 and was trained with a longer reinforcement learning run on a harder set of tasks. The training mix emphasized problems that can take hours to complete, pointing to coding agents, professional document creation, technical troubleshooting, and other workflows where models need to hold coherence across many steps.
Benchmark results show the biggest gains in software engineering, terminal work, electrical engineering, legal work, and clinical reasoning. On CursorBench 4.0, Grok 4.7 scored 46.3%, up from 40.4% for Grok 4.6. On DeepSWE v1.1, it reached 71.0% in high-effort mode, compared with 65.2% for Grok 4.6. On Terminal-Bench 4.0 it scored 38.0%, nearly double Grok 4.6's 20.3%.
Many AI coding tools are moving beyond autocomplete toward longer autonomous loops, where speed and price are only part of the equation. A model also needs to inspect its own work, recover from mistakes, use tools reliably, and stay on the user's objective during longer sessions.
Document and presentation creation is another priority. Grok 4.7 improves over Grok 4.6 on GDPval and AA Briefcase, two benchmarks that test professional knowledge work across fields such as law, nursing, and financial analysis. In AA Briefcase v1.1, Grok 4.7 scored 1,657, ahead of Grok 4.6 at 1,546 and GPT-5.6 Sol Max at 1,487, and below Fable 5.1 Max at 1,678.
Safety is a large part of the release. SpaceXAI said Grok 4.7 uses an entirely new safeguard stack and is the strongest model it has tested on refusals and jailbreak resistance. In cybersecurity, Grok 4.7 allowed only 3.3% of risky dual-use prompts through on HackerBench v0.3 while keeping low refusal rates for legitimate security work. SpaceXAI has begun giving select cybersecurity partners invite-only access to Grok 4.7's red-team capabilities for defensive research.
"It is the strongest model we’ve tested on refusals and jailbreak resistance. In dual-use domains like cybersecurity and biological work, it leads on both utility for benign tasks and safe refusal on dangerous ones, topping LatchBio’s biosafety benchmark at 62.4%."
The release gives developers another frontier model for coding and agentic knowledge work. By keeping base pricing aligned with Grok 4.6 while improving benchmark scores, SpaceXAI is competing on price-performance as much as raw capability.
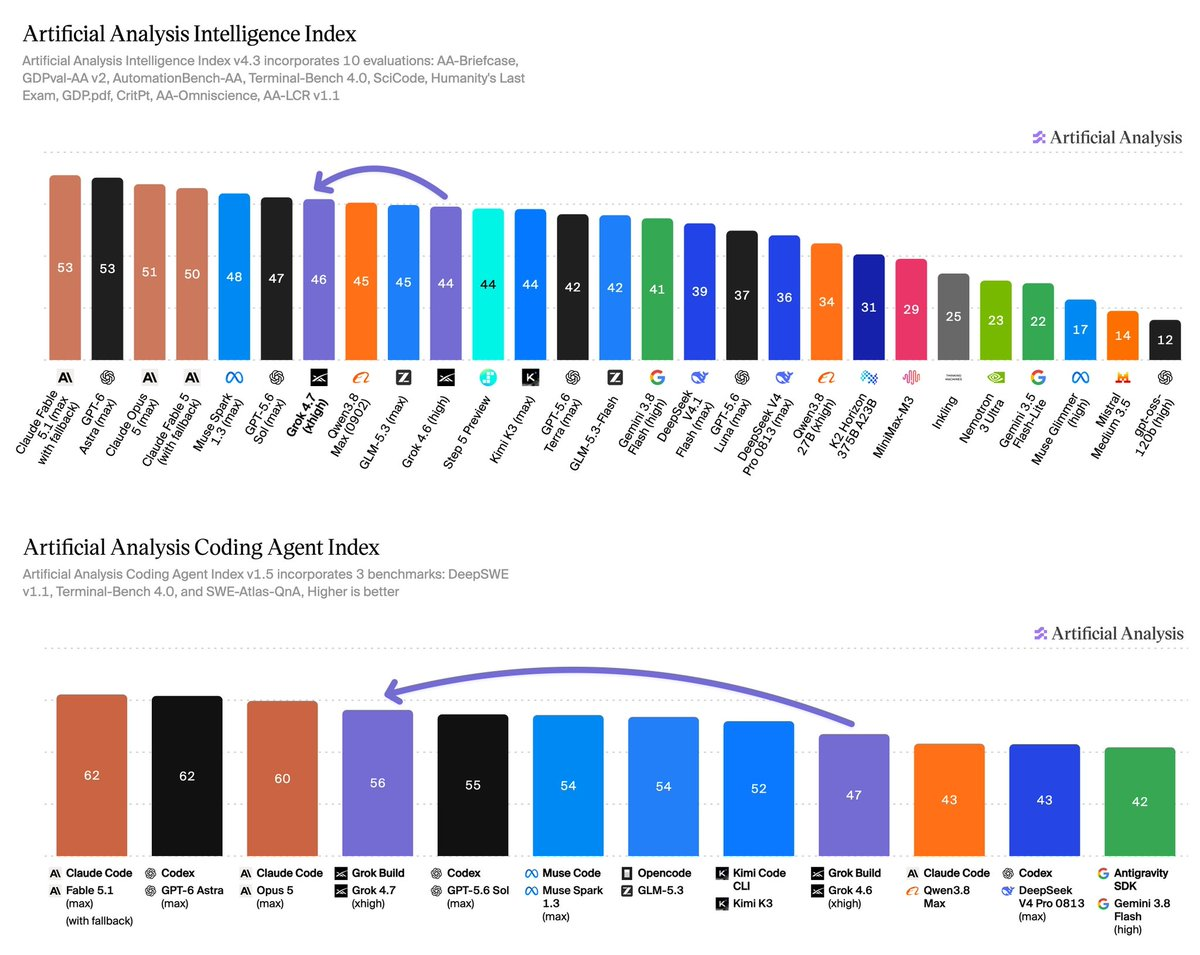
Celebrating the launch, Elon Musk noted that "Grok 4.7 places @SpaceXAI as third, after Anthropic & OpenAI, for agentic coding. When factoring in that Grok is significantly faster & lower cost, it’s a great choice for your everyday workhorse."