
Table of Contents
Chutes has added Qwen3.8 2.4T A95B, the open-weights model behind Qwen3.8 Max, to its inference platform. Access costs $2 per million input tokens and $6 per million output tokens, matching Chutes’ pricing for Max.
It is Qwen’s first openly released Max-class model, available to developers through a hosted API. The model has 2.4 trillion total parameters, with 95 billion active per token, a roughly 262,000-token context window, and always-on reasoning.
The model uses a mixture-of-experts architecture, which activates a subset of its parameters for each token rather than the entire network. Its expert layers select 10 routed experts alongside one shared expert from a design with 512 routed experts.
The open-weights version accepts text only and cannot switch reasoning off. Qwen3.8 Max, the official API version built on those weights, adds vision input, a non-thinking mode, built-in tools, and a 1-million-token context window by default. The open model’s native context is 262,144 tokens, with support for extension to about 1 million tokens.
Qwen publishes its benchmark results under the Qwen3.8 Max name. Those results include 86.6 on Terminal Bench 2.1, compared with 84.6 for Opus 4.8 and 88.8 for GPT 5.6 Sol, and 81.9 on WideSearch, compared with 81.2 for Fable 5 and 72.9 for Opus 4.8. These are Max results, not separate measurements of Chutes’ hosted open-weights deployment.
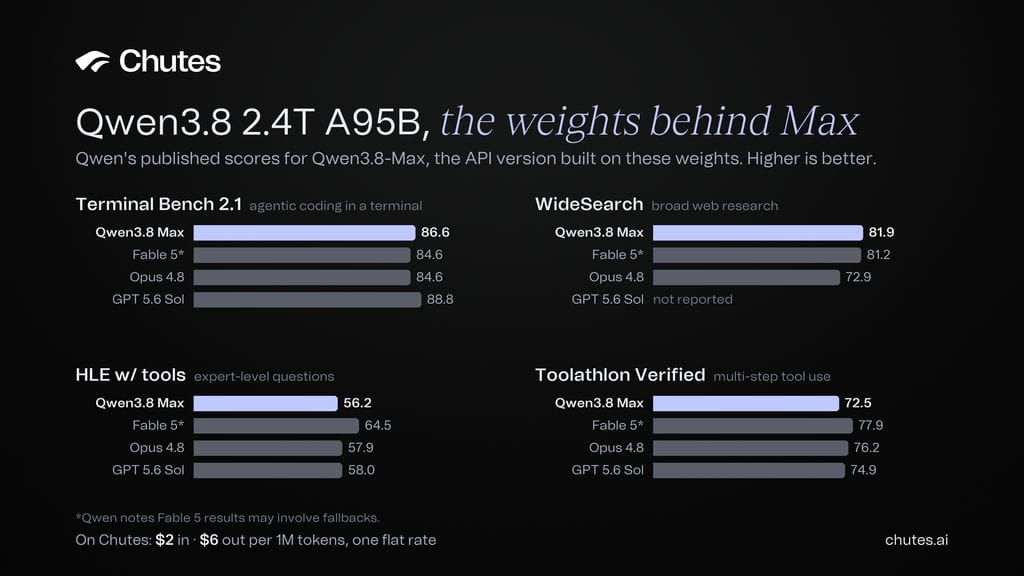
Max trails those three comparison models on HLE with tools, scoring 56.2, and Toolathlon Verified, scoring 72.5. Qwen reports that its Terminal Bench result uses the Claude Code harness, while comparison scores use other harnesses; WideSearch also uses different harnesses for Qwen and external models. The benchmark notes say Fable 5 results may involve fallbacks.
Developers can use the Chutes model endpoint with an OpenAI-compatible SDK, a Chutes API key, and the model identifier Qwen/Qwen3.8-2.4T-A95B. The API base is https://llm.chutes.ai/v1, with requests sent to POST /v1/chat/completions. Cached input costs $0.25 per million tokens.


